Appearance
Qwen Image 2.1 Turbo mixed-precision qualification
Built with Qwen. This report covers a mixed-precision conversion of the official Qwen Image 2.1 Turbo checkpoint, not the base Qwen Image 2.1 model or a Turbo LoRA. The original Qwen Research License applies.
Conversion, artifact verification and public publication are complete. All 25 bundle files were verified by size and SHA-256 at immutable revision d8276b786f94a4e8944189cc181e839e31759ab5, including anonymous access after publication. Limited trained-checkpoint execution passes the five cases below. The report and receipt include bounded runtime observations. The machine-readable receipt records weight hashes, header-audit results, native binary identity and these gates.
Provenance and format
- Source:
Qwen/Qwen-Image-2.1-Turboatd65dbc9a7e8f6b5479e33dee6030eaab2a906509. - Artifact: Sawfwair/Qwen-Image-2.1-Turbo-MLX-Mixed-4bit.
- Conversion:
scripts/model-conversion/convert_qwen_image21_turbo_mlx.py, MLX 0.32.2 CUDA, cuDNN 9.12.0.46; conversion ran on an ephemeral RunPod GPU. - Transformer block linear weights: MLX affine Q4/group-64.
- Encoder linear weights: MLX affine Q8/group-64.
- Embeddings, VAE, normalization, transformer input/output, timestep and modulation layers: original BF16. The unused language-model output head is omitted because native conditioning returns hidden states.
- Original eight-step sigma grid and CFG 1 defaults are preserved.
The conversion records source file hashes and per-layer weight reconstruction errors in QWEN21_CONVERSION.json. Weight reconstruction does not measure image quality. The bundle includes the upstream license, required Notice, upstream model card, modification notices, executed converter and SHA-256 checksums.
The final redistribution bundle is 14,252,544,800 bytes (14.25 GB). All transferred files matched the conversion host's SHA-256 checksums before packaging corrections. The corrected package records those metadata changes without changing weight payloads. The header audit passed against the original pinned tensor schemas: 341 Q8 encoder layers, 224 Q4 transformer layers, and 238 unchanged VAE tensors. Tensor closure, packed dtype/shapes and shard ownership were checked separately from checksum integrity.
The temporary RunPod pod and its attached temporary disk were terminated after local preservation; the provider inventory confirmed the pod absent.
Inference uses native Swift/MLX. Packed weights stay UInt32 and execute with quantized matrix multiplication; no full-precision model expansion or Python inference sidecar is needed. Components load and release in stages.
Local code verification
The Qwen-focused tests passed: 22 tests, two opt-in skips, zero failures. The packed Q4/Q8 transformer path matches explicitly dequantized weights on common inputs and rejects malformed packed weights, scales, biases and unsupported packing. The loader test verifies preservation of UInt32 values through disk loading. These checks use small fixtures rather than trained-checkpoint images.
The repository gate passed 5,351 XCTest cases (441 opt-in skips) plus 193 Swift Testing cases, strict lint, CLI help and hygiene checks. The documentation site also built successfully. Hosted CI and a released application are separate gates.
Trained-checkpoint local execution
The isolated PR implementation completed all five native Swift/MLX CLI cases at source commit 6a10257e64fb754ca5e75b7226a2a04fc18a61ef, based on current main at 0f0f7b9f2a0d9801ca0098ca0d6d6dd020b6efab. The source was committed before these runs. Each used the public checkpoint revision above, eight steps and CFG 1, with the standard memory-admission guard. The receipt records the tested binary hash.
| Case | Seconds | Peak process footprint (GiB) |
|---|---|---|
| smoke-512 | 27.7 | 9.14 |
| replay-512 | 22.8 | 9.12 |
| quality-1024 | 97.0 | 20.58 |
| text-1024 | 141.7 | 20.63 |
| edit-512 | 53.8 | 10.35 |
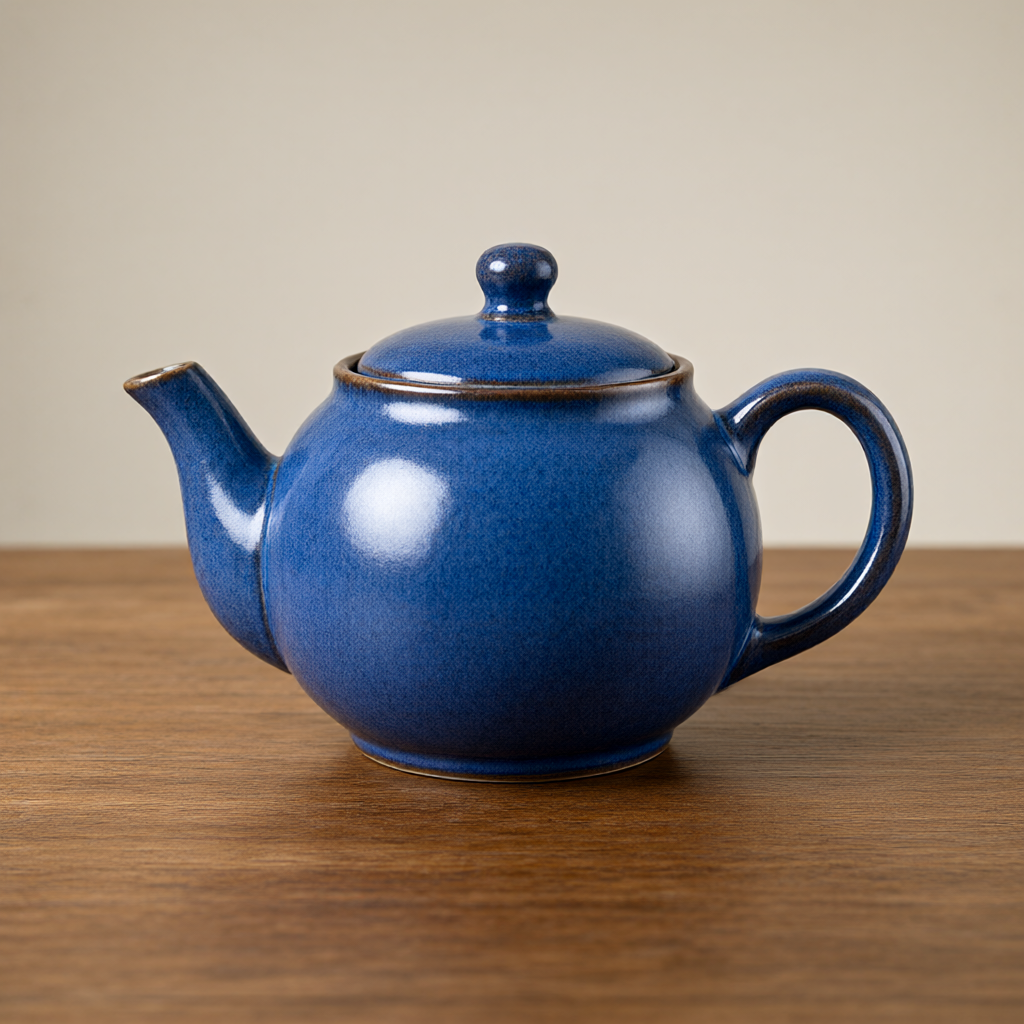
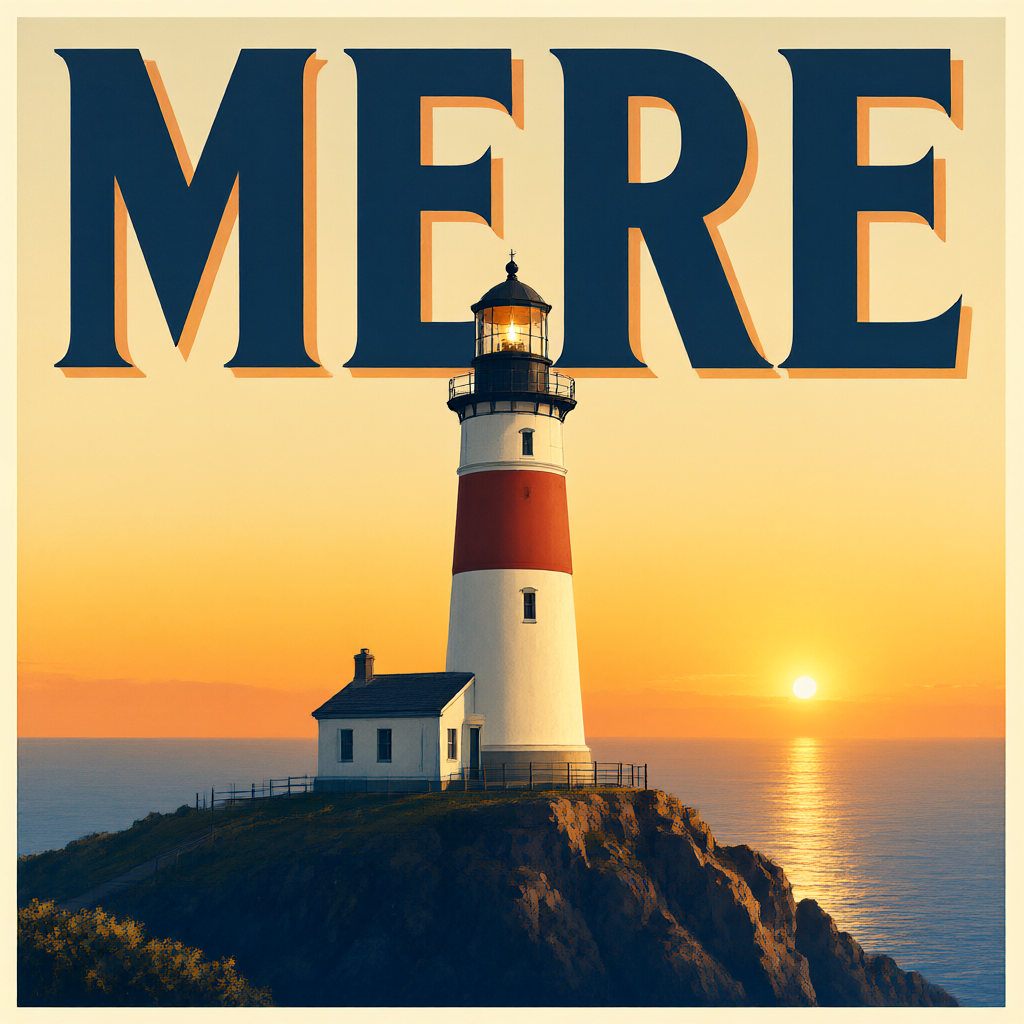
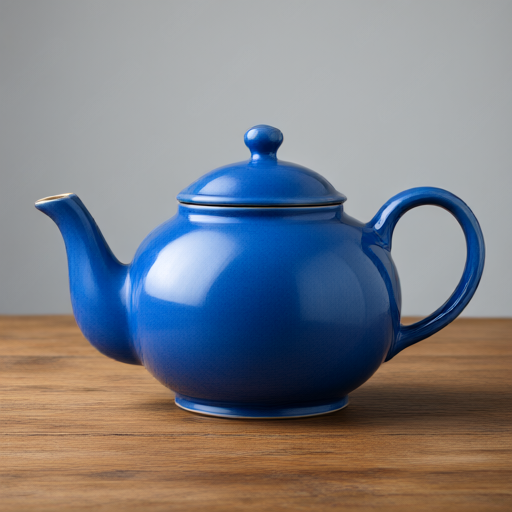
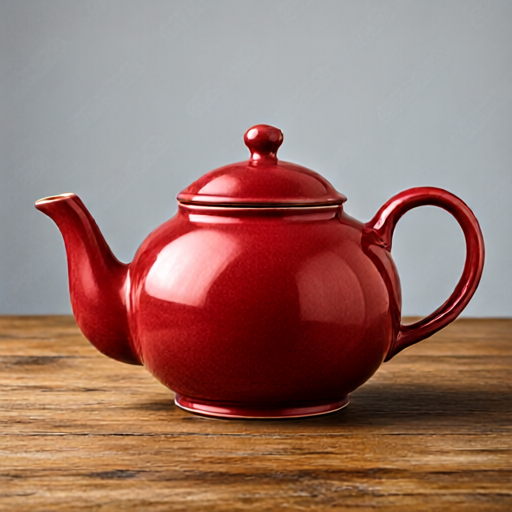
Elapsed times are single observations during concurrent validation work, rather than throughput guarantees. The 512-pixel replay produced identical pixel and PNG SHA-256 hashes. Every revalidated image matched the earlier inspected output pixel-for-pixel. Visual checks found coherent blue teapots, a legible MERE poster heading, and a blue-to-red reference edit retaining overall shape, composition, table and lighting with small texture changes. All outputs are correctly sized RGBA PNGs.
The highest observed OS process footprint was 20.63 GiB. This includes GPU allocations and caches; it is not whole-machine usage or a minimum-memory guarantee. These cases qualify bounded 512/1024 generation and one-reference editing with sufficient admission headroom. They do not qualify 2048-pixel output, multiple references, transparent output, broad prompt quality, or BF16 Turbo equivalence. quality_qualified remains false.
The full repository gate passed against the isolated source implementation. Raw case receipts, logs and progress events are retained locally; the downloadable receipt records prompts, seeds, checkpoint/source/binary hashes, image hashes and memory/timing observations. Released-app qualification and hosted CI are separate.
Inspected samples